Enterprise RAG & Search
Hybrid semantic retrieval, pgvector indexing, and deterministic context synthesis for private enterprise data.
We build production-grade Retrieval-Augmented Generation (RAG) engines that query internal PDFs, technical documentation, ERP databases, and customer records with sub-second latency and zero hallucinations. Self-hosted inside your private VPC with full data sovereignty.
High-Precision Enterprise Knowledge Retrieval
Eliminating hallucinations through multi-stage retrieval pipelines: dense semantic embeddings, sparse keyword matching, cross-encoder reranking, and citation verification.
Hybrid Dense & Sparse Retrieval
Combining dense vector embeddings with BM25 keyword matching to capture semantic intent and exact alphanumeric strings (SKUs, part codes).
Context-Aware Document Chunking
Hierarchical parsing preserving tables, header hierarchies, footnotes, and metadata across multi-page enterprise PDFs.
Cross-Encoder Neural Reranking
Neural rerankers that filter out irrelevant context windows before synthesis, minimizing prompt token bloat and hallucination risk.
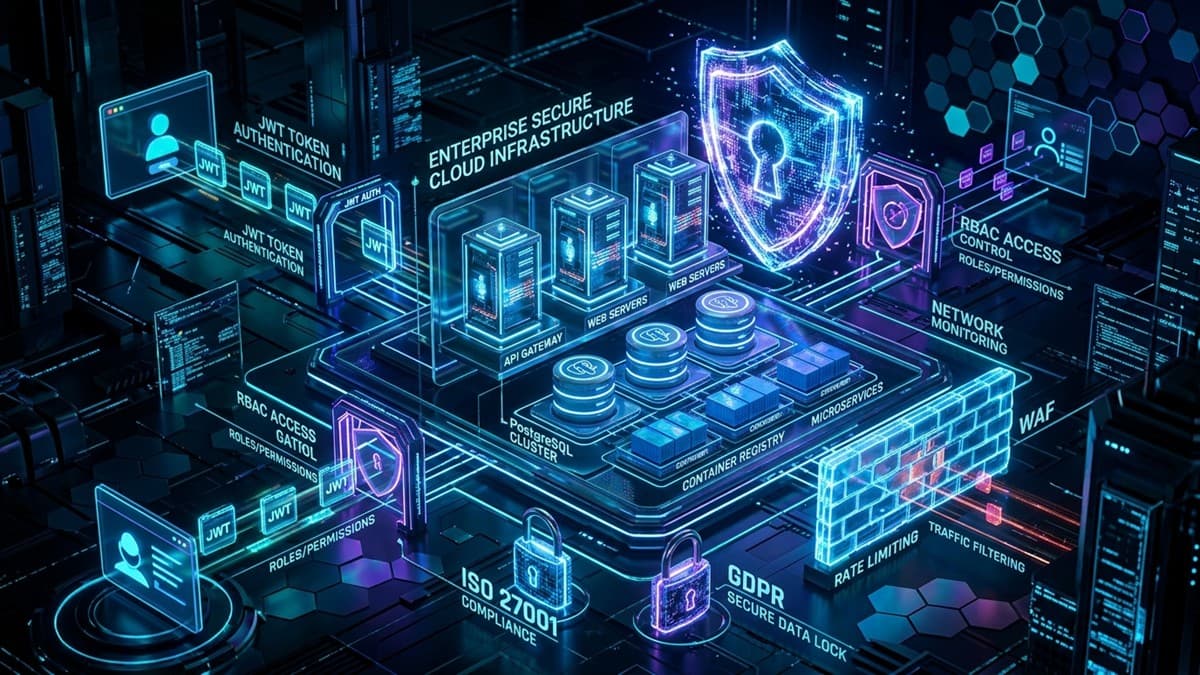
Private VPC Air-Gapped Security
Self-hosted embedding generation and vector databases running behind your corporate firewall with zero cloud model training.
Decoupled Architecture Dataflow
A 4-tier breakdown of how requests, state mutations, and data queries flow through this production stack.
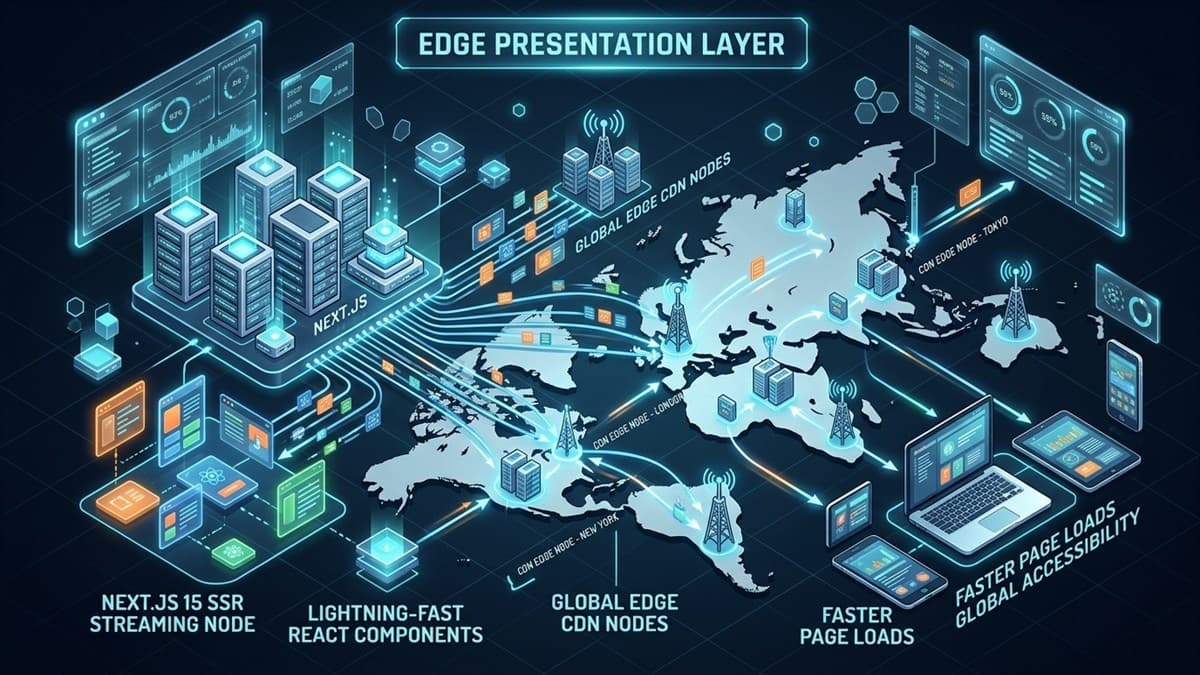
Unstructured Document Pipeline
High-throughput document extractors parsing complex PDF layouts, tables, and OCR scans into structured semantic chunks.
Vector Embedding Generator
High-throughput embedding workers generating dense 1536-dim vector representations with hierarchical metadata indexing.
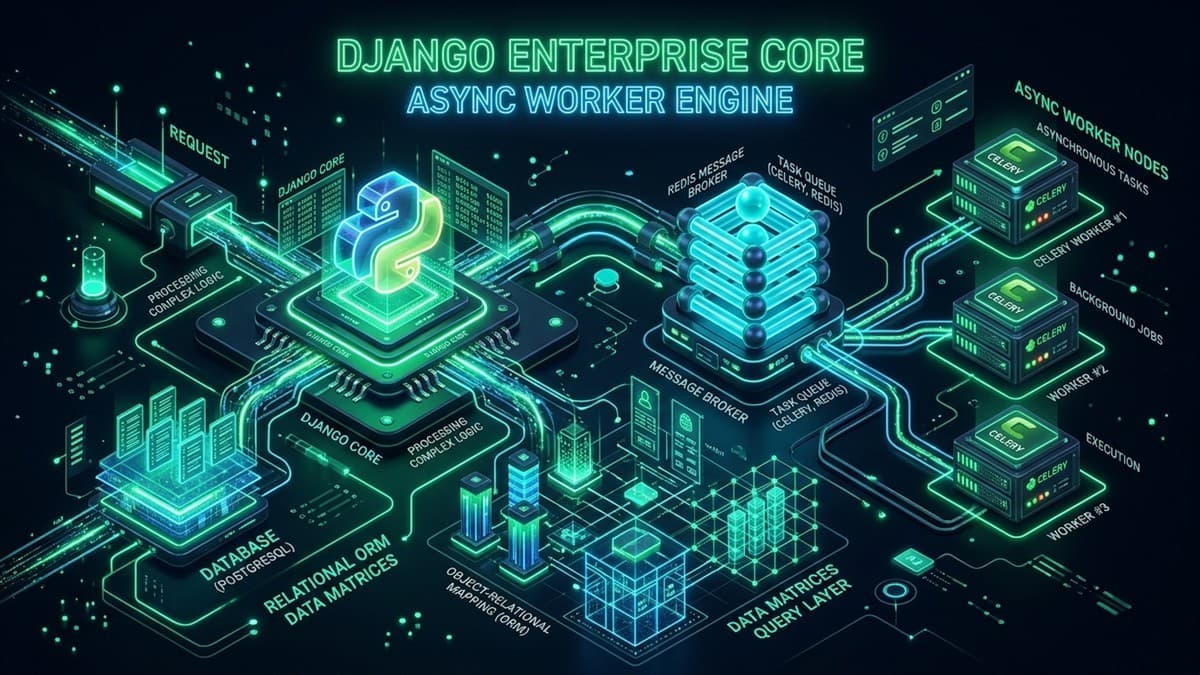
pgvector & Qdrant Cluster
Self-hosted PostgreSQL pgvector or Qdrant cluster executing sub-second HNSW approximate nearest neighbor searches.
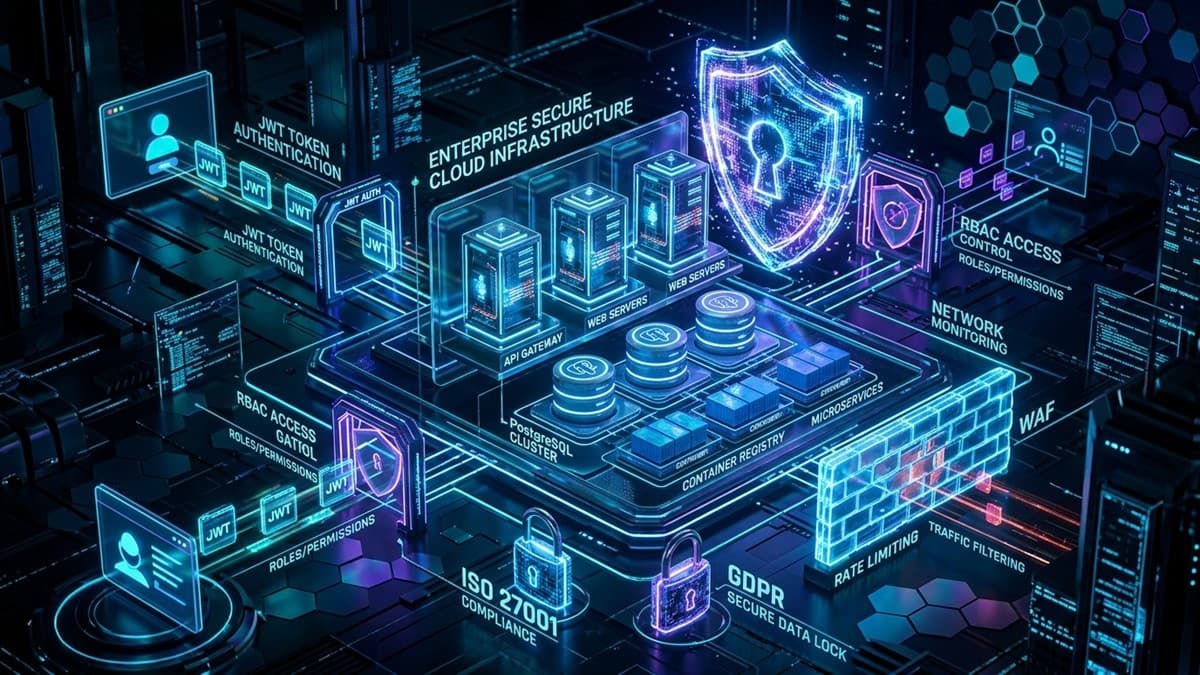
Citation-Grounded LLM Gateway
Prompt synthesizers enforcing strict context-only reasoning, generating exact page-number footnote citations for every statement.
Core Engineering Deliverables
Every component is backed by strict type contracts, comprehensive test suites, and transparent documentation.
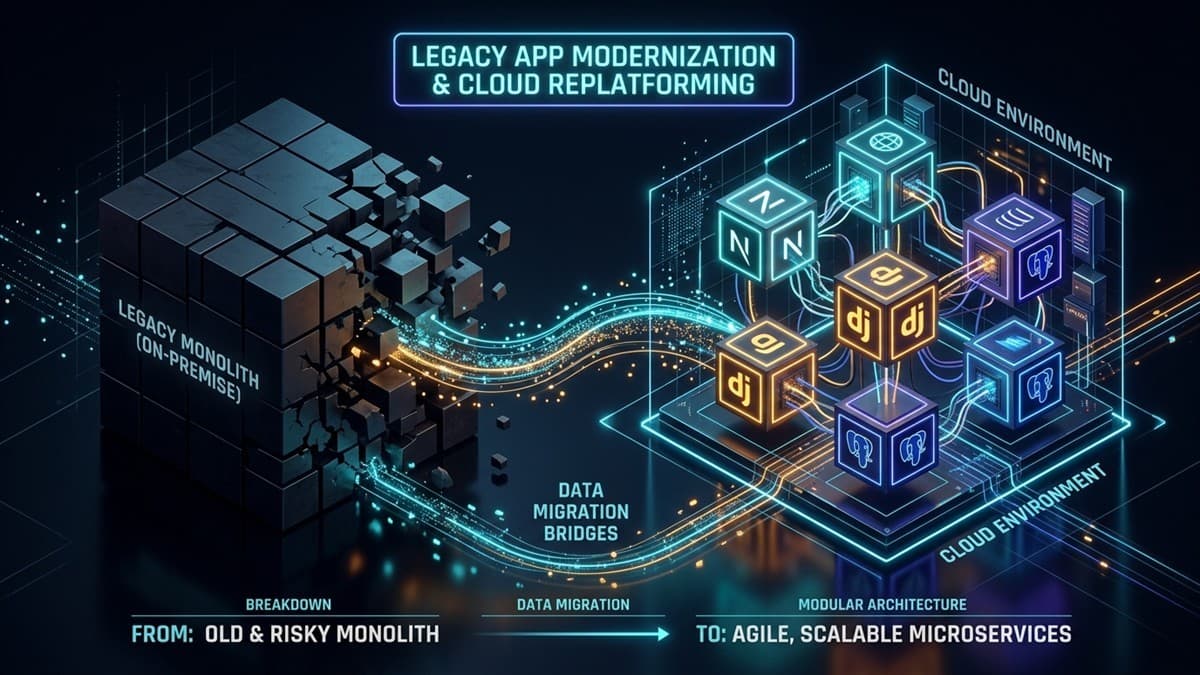
Automated Document Ingestion Engine
Continuous ingestion pipeline watching Cloud Storage, SharePoint, and Google Drive for new PDF, DOCX, and CSV uploads.
- Table-aware PDF layout parser
- Automated metadata extraction (dates, authors, departments)
- Incremental chunk hashing to avoid re-embedding unchanged files
- OCR fallback for scanned physical documents
Hybrid Semantic Search & Reranking Core
Combined BM25 + dense vector retrieval system with neural cross-encoder reranking for maximum answer recall.
- HNSW vector indexing on pgvector/Qdrant
- Reciprocal Rank Fusion (RRF) for hybrid scoring
- Cross-encoder reranking filter
- Semantic query cache in Redis for sub-50ms repeat lookups
Continuous RAG Triad Evaluation Suite
Automated regression testing framework measuring Context Relevance, Groundedness, and Answer Relevance on every dataset change.
- Ragas / TruLens automated evaluation metrics
- Synthetic question-answer benchmark datasets
- Nightly CI/CD hallucination regression tests
- Latency and token spend telemetry per query
Enterprise Knowledge Portal UI
Responsive Next.js web application with interactive citation previews, document highlights, and access control filtering.
- Real-time streaming answer generation
- Interactive inline footnote citations with PDF page preview
- Department-based access control (RBAC)
- Thumbs up/down feedback logging for continuous optimization
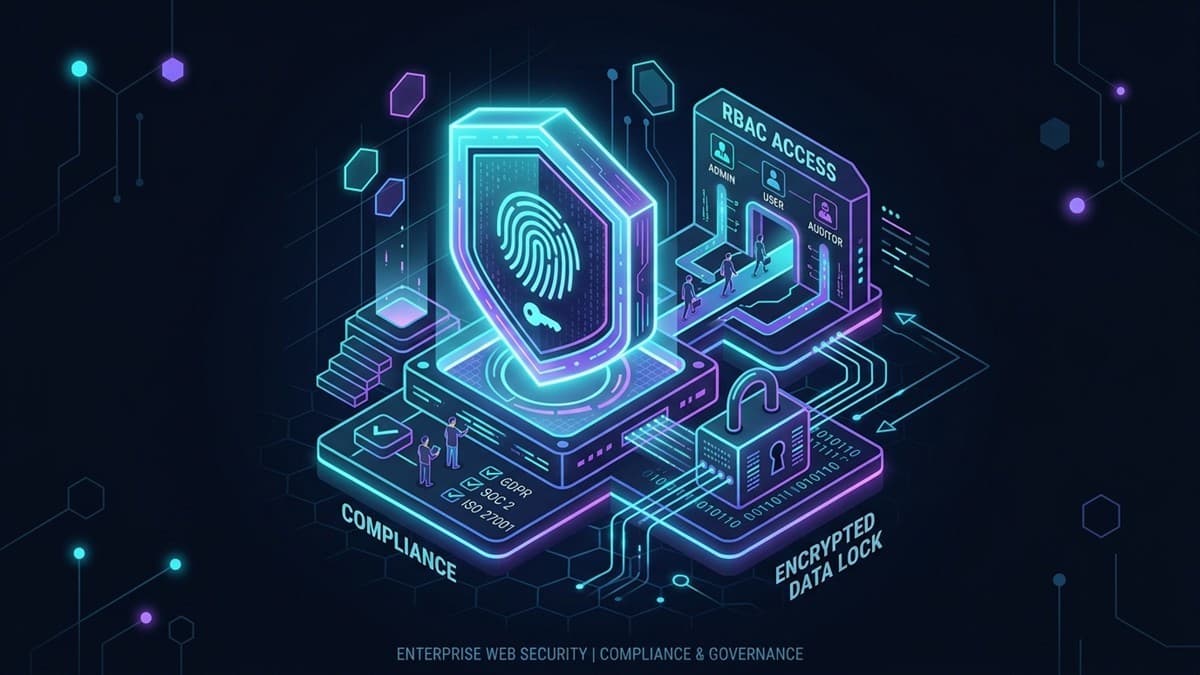
Private VPC & Air-Gapped Cloud Deployment
Complete Docker Swarm / Kubernetes deployment running on your internal cloud infrastructure with zero external data sharing.
- 100% self-hosted vector database cluster
- Encrypted data at rest (AES-256) and in transit (TLS 1.3)
- Zero data training agreements with private API gateways
- Automated database backup and point-in-time recovery
Our 5-Phase Engineering Lifecycle
Predictable 2-week sprint cycles with weekly staging deployments, automated test reports, and transparent milestones.
Document & Data Audit
Analyze document formats, metadata structures, and domain-specific terminology.
Chunking & Embedding Design
Select embedding models, chunk boundary strategies, and hybrid search weights.
Pipeline & Vector Store Build
Implement pgvector indexing, background parsers, and reranking modules.
RAG Triad Benchmarking
Run automated evaluations on golden question sets to tune precision and eliminate hallucinations.
VPC Deployment & Portal Launch
Deploy behind corporate firewalls with RBAC security and real-time query analytics.
The Trade-Off Matrix: When to Choose & When to Avoid
We never recommend an architecture blindly. Here is our perspective on where Enterprise RAG & Search excels and where simpler alternatives make more sense.
Strong Fit / Recommended When:
- Your enterprise has vast repositories of unstructured PDFs, policy documents, CAD specs, or tickets that employees spend hours manually searching.
- You cannot tolerate generic model hallucinations and require explicit footnote citations for every generated answer.
- You require hybrid retrieval (dense vector embeddings + sparse BM25 keyword matching) to handle exact SKU numbers and technical acronyms.
- You cannot send internal confidential IP or customer records to third-party SaaS search clouds.
Poor Fit / Look Elsewhere When:
- ×Your data fits entirely in a standard relational database with straightforward SQL filter requirements.
- ×You only need basic keyword full-text search with simple Postgres or Elasticsearch queries.
Total Cost of Ownership (TCO) Comparison
Compare dedicated engineering and self-hosted infrastructure against recurring manual operational overhead or closed SaaS subscriptions.
Fixed monthly cost on your private cloud/VPC. Does not penalize workflow volume or operational scale.
Recurring SaaS seat licenses or manual labor overhead with high error rates and zero intellectual property ownership.
Replaces high recurring per-user SaaS licenses with owned, private infrastructure that scales across your entire workforce with zero incremental license fees.
National Industrial Equipment Manufacturer: Technical Knowledge Search over 40,000 Engineering Blueprints
Replaced a 15-minute manual technician lookup workflow with a sub-second natural language query engine that returns exact component diagrams and torque specs with 99.1% accuracy.
Recommended Production Stack
pgvector, Qdrant, PostgreSQL
Sub-second HNSW nearest neighbor searches with native relational metadata filtering.
FastEmbed, BGE-Large, Cohere Rerank
Dense semantic representations combined with cross-encoder neural context filtering.
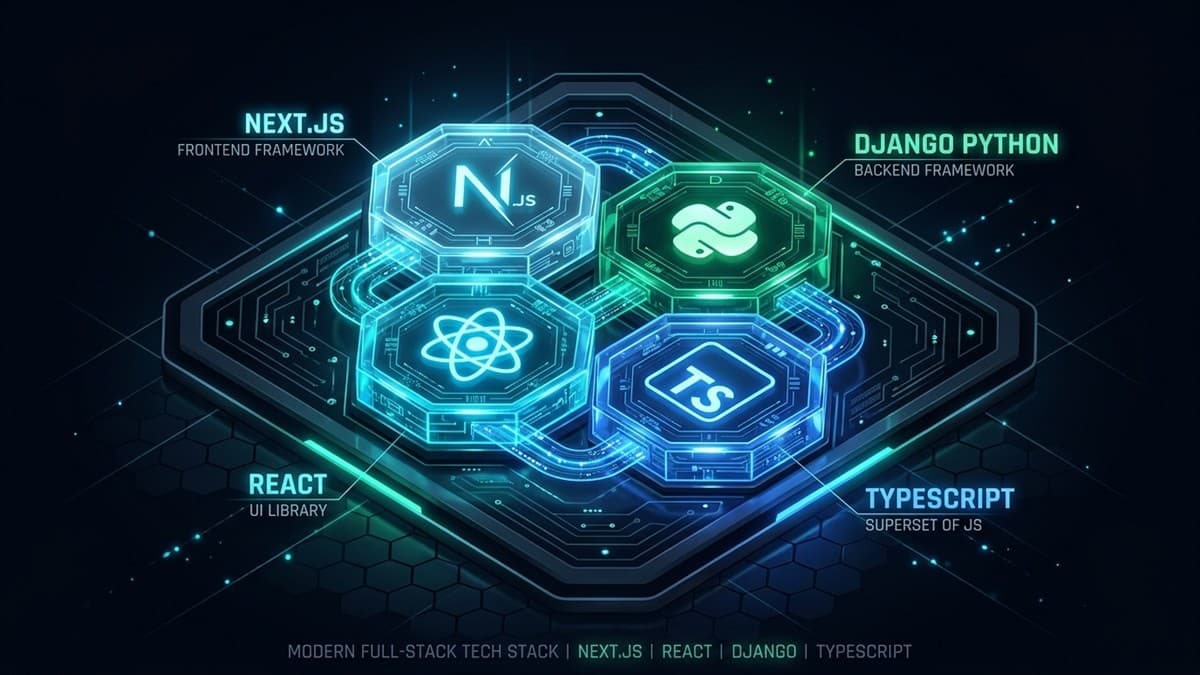
Next.js 15, React 19, Tailwind CSS
Streaming UI with instant inline footnote citations and document viewers.
Agency Architecture Insight
Naive RAG fails on tabular data and specialized domain acronyms. Production-grade RAG requires hybrid retrieval combining dense vector similarity with sparse BM25 indexing and cross-encoder neural reranking.
Frequently Asked Technical Questions
Transparent answers on validation guardrails, latency benchmarks, data privacy, and integration roadmaps.
AI & Intelligent Systems
AI agents, automation, intelligent systems and integrations that transform how you operate.
Evaluate Enterprise RAG & Search for your enterprise
Schedule an architecture discovery consultation to review your workflow schemas, integration points, and deployment feasibility.